:)) With the constraints on scale and reload time I don't dare to weigh in, since the projects I've worked on weren't that strictly large, but I'd still like to contribute a little. My idea is to store the first version as a full save, then record each later edit as a diff with its position in a version table. Every so often, when the user leaves the document or after a handful of edits, a new full save folds the earlier diffs in. Two tables hold the document and its versions. To rebuild an old version you take the nearest full save and replay the diffs forward.
-
Idea for handling it:
- Call the first version version 1 – fullSave 1
- For each subsequent edit, store the edit content and edit position in a version table
- Set a rule: when the user leaves the document, or after some number of edits (5, 10, ...), or when the amount of change is large enough, create a new fullSave that includes the earlier edits
- One change is counted on each autosave or manual user save (if autosave runs every 5s, just count autosaves)
-
In the database, there are 2 tables:
-
- The basic document information (id (PK), current version (FK), subject, owner, times, etc.)
-
- The version information table, which contains:
- version id (PK)
- original document id (FK)
- previous version id (depending on the id rule – if ids are based on the original document id it isn't needed, but it costs an extra step to work out the previous version)
- change: a link to a JSON file containing information such as (change type: modify, add, delete; change position; change content) OR some other content format, but I find JSON works better and has helper functions that are quick
- fullSave version id: id of the most recent fullsave version
- fullsave content: the complete current content of the document; if the rule for creating a fullsave hasn't been met yet, this is null
- other information: edit time, who edited, ...
-
-
To reconstruct a version that isn't a fullsave, use the id of the nearest fullsave version and the previous version ids (which is why each version stores its previous version id)
-
For the cache strategy, store the most recent fullsave version and the change versions, until another fullsave is created
I'm mostly here to learn from everyone and don't know much about system design. But I do know a bit about algorithms: when I studied the Persistent Segment Tree – a kind of segment tree – when there is a change at a node, you don't copy the old nodes exactly into the new ones; instead you only create new nodes for the parts that differ, and the identical parts still point back to the old nodes. That's just a tiny bit of information. I hope reading this idea gives you all some ideas.
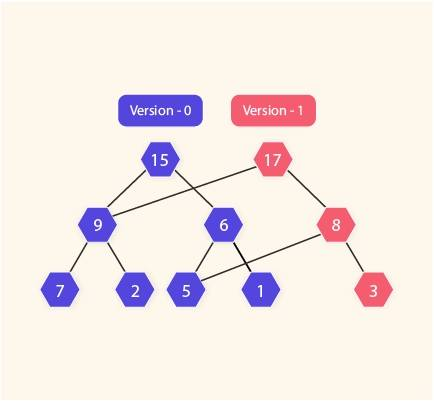
Text editors usually use the Rope data structure, though in practice it's customized to support many features such as change detection, diffing, etc.
I've read about git internals, and git works on this same mechanism: changed content is recorded in blobs.
See also: Technical Solutions · 3 2 1 Backup Strategy